Lamp II · In progress Checked
kanhe
A claim checker for Swiss federal voting booklets. It answers entailment, neutral or contradiction, and shows the booklet sentences it relied on.
Claim · German
Der Bundesrat rät der Bevölkerung, die e-ID abzulehnen.
The Federal Council advises the public to reject the e-ID.
Booklet · French · vote of 28 September 2025 · page 31
Pour toutes ces raisons, le Conseil fédéral et le Parlement vous recommandent d’accepter la loi sur l’e-ID.
For all these reasons, the Federal Council and Parliament recommend that you accept the e-ID law.
kanhe · contradiction · quote found in the booklet, letter by letter
- Room
- Swiss federal voting booklets, in German, French and Italian
- Model
- swiss-ai/Apertus-v1.5-8B, which translates and judges
- Retrieval
- BM25, which picks the paragraphs the model reads
- Made for
- Hack Apertus Online · Track 2A · OST challenge: multilingual natural language inference over Swiss official voting booklets
- State
- In progress. Submission due 16 October 2026, 12:00 CEST. Not judged yet.
- Made by
- Hongyu Zhou, solo
- Licences
- Code Apache-2.0 · report and documentation CC-BY-4.0 · cache of model answers CDLA-Permissive-2.0 · benchmark MIT (OST) · the booklets are official publications of the Swiss Federal Chancellery
- Links
- None yet. The repository is not public.
- Entry checked
What it does
kanhe takes a claim and a Swiss federal voting booklet, in any mix of German, French and Italian, and answers entailment, neutral or contradiction.
For a booklet PDF (task A), it reads the pages of the vote in question, translates the claim when its language differs from the booklet’s, lets BM25 pick the eight most relevant paragraphs, and asks Apertus-v1.5-8B for a label and the sentences behind it. For a passage (task B), the model reads the three most relevant paragraphs and the first one.
It checks that every quote is in the booklet, letter by letter, and quotes in task A carry their PDF page.
Numbers
| Task | Input | Macro-F1 [95% CI] | Tokens per claim | Latency per claim |
|---|---|---|---|---|
| A | Claim, booklet PDF, name of the vote | 0.913 [0.885, 0.941] | 1,272 | 0.91 s |
| B | Claim, passage | 0.967 [0.946, 0.983] | 923 | 0.85 s |
On 70 dev rows, giving the model the whole PDF scored 0.538 at 42,495 tokens per claim. kanhe scored 0.864 on the same rows with 3% of the tokens.
Source · kanhe README, task A, dev rows
In task B, kanhe is statistically level with giving the model the whole passage: 0.967 against 0.973, a paired difference of −0.006 [−0.021, +0.007], with 42% of the tokens.
Source · kanhe README, held-out split
Assembly drawing
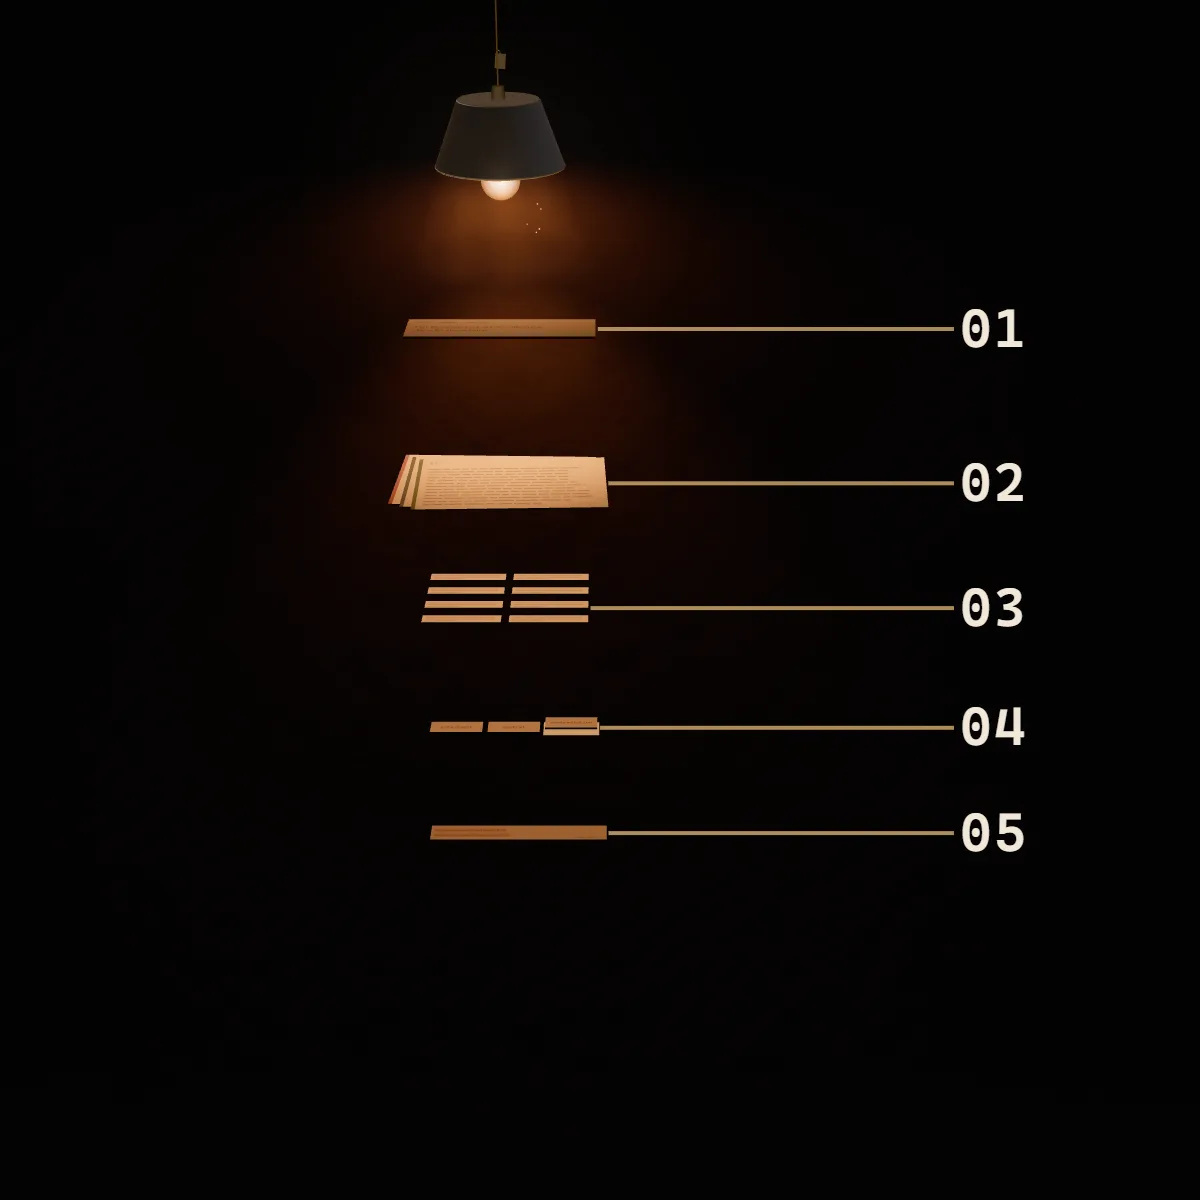
- 01 The claim: benchmark item 1021, in German
- 02 The booklet, in German, French and Italian
- 03 The eight paragraphs BM25 picks for the model to read
- 04 The label: entailment, neutral or contradiction
- 05 The quote, checked against the booklet letter by letter, with its page
A drawing of how kanhe is put together, made for this site. It is not a screenshot.
Assembly list
Installed
- Both challenge tasks, answered through the organisers’ evaluation contract: Docker, linux/amd64, no GPU
- A letter-by-letter check of every quote; quotes in task A carry their PDF page
- Six example cases that replay from the cache with make demo, no API key
- Every table in the technical report, recomputed from cached answers with make run
Not installed yet
- A public repository
- Official judging
Where to poke holes
- Not every answer carries a passing quote: 90% in task A and 96% in task B of entailment and contradiction answers do.
- Task A is weakest on German claims against German booklets: macro-F1 0.789 on 37 rows.
- In task A, 4 of the 331 model answers could not be parsed.
- The technical report lists the scores by language, two baselines that never read the booklet, and the limitations.
Backstage
kanhe was made for Hack Apertus Online, Track 2A. Its configuration was fixed on the 2020 to 2024 booklets, then run once per task on the 2025 and 2026 booklets. Model answers are cached, so the six example cases replay with make demo and every table in the report is recomputed with make run, without an API key or a GPU. The benchmark is OSTswiss/MNLIoverSwissVotingBooklets, released under the MIT licence.